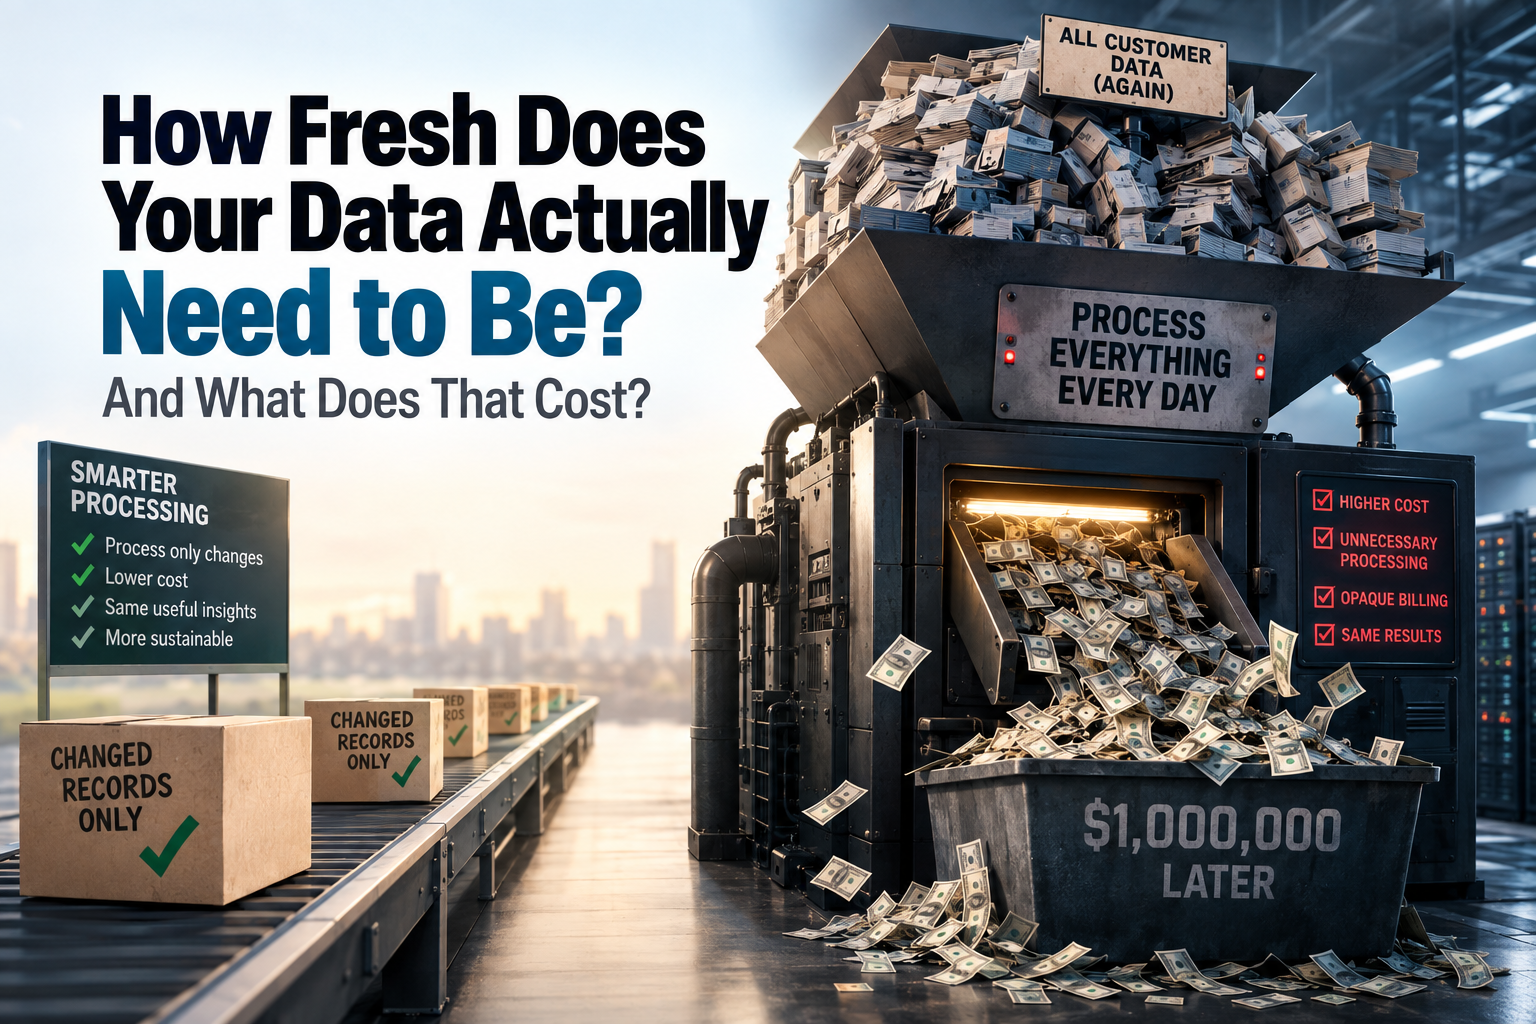
How fast is this data actually changing?
How fresh does the answer really need to be?
What does each pass through the data actually cost?
Those questions sound obvious after the fact. They were not obvious while the system was being built.
And that got expensive.
1. The Dataset Was Large. The Rate of Change Was Not.
The organization had a large customer population and wanted sophisticated analysis of customer relationships and behavior. I had already built much of that analysis using an analytics platform we already had.
Another division had hired an outside consulting company as specialists in a newer cloud platform. I was new to the organization, and the people who hired the consultants did not know I was already building similar analytics elsewhere using a closely related tool.
The consultants got to work gathering requirements and information. Somewhere along the line, someone higher up thought I might be able to help, so I joined the twice-weekly meetings and contributed where I could.
It quickly became apparent that the analysis was not simple. We were trying to understand customer behavior, relationships, and associations across a very large population. AI capabilities in the new platform were being used because this was exactly the kind of complicated analytical work they were good at.
I had already done a substantial amount of the underlying work in the existing environment, so I found myself increasingly helping the consultants understand the data and how the analysis needed to work.
Eventually the head of the consulting team asked to meet with me privately. She asked for my code and my existing data implementations. That surprised me. But in the interest of “we’re all on the same team,” I gave it to her. All of it.
I also gave her a warning: Be careful with the processing. The new platform charged credits based on processing activity, and processing the entire customer population repeatedly could become extremely expensive.
The response was essentially: We’ll get to that.
They never did.
When I later saw the finished implementation, it resembled just about exactly what I had already built. That was not inherently a problem. If the logic works, reuse it. But there was one enormous difference: They were processing the entire customer population every day.
I had begun with full-population processing too. My existing platform did not charge for individual processing activity in the same way, so initially there was little financial consequence. But I discovered that the customer records simply did not change very often.
Based on that, I moved the full refresh to weekly, then monthly, and eventually added logic that picked up only accounts that had actually changed. Data volume and rate of change are not the same thing.
If you have five million records, the first question should not automatically be, “How do we process five million records faster?”
It should be: “How many of those five million records actually need to be processed?”
I raised the concern again, this time with internal leadership. I told them that processing the entire population every day was unnecessary and potentially prohibitively expensive. And I was assured that both the platform vendor and the consulting company said we had plenty of credits.
So the system went live.
2. Real Time Is Not Automatically Better
When I gently questioned the decision to process the entire population every day, I was told Sales and Marketing wanted “real-time” data, or as close to real time as they could get.
In my experience, sales organizations almost always want real-time data. They want to know immediately when a deal changes, when an opportunity closes, and often how that sale affects their compensation. From the salesperson’s perspective, I get it. But personal desire for immediate information is not the same thing as an organizational requirement for real-time analytics.
The obvious question is: Why or why not real time? True real-time systems can be expensive to build, integrate, monitor, troubleshoot, and maintain. The more systems involved, the more complicated the problem becomes. Once an organization becomes accustomed to supposedly instantaneous data, even a short interruption can suddenly feel catastrophic.
So the more important question is: What decision becomes better because this number is 30 seconds old instead of a day, a week, or even a month old? Operational and strategic analytics are very different. A salesperson may genuinely need to know that an order closed, inventory disappeared, or an account status changed five minutes ago. But if leadership is trying to understand customer behavior, identify long-term sales trends, evaluate product performance, study customer segments, or decide where resources should be allocated, changing course because a dashboard moved at 2:17 p.m. is usually not sophisticated management.
Real-time analytics, when applied improperly, can turn normal variation into apparent urgency. Strategic decisions need context. They need enough observations to distinguish a trend from a fluctuation.
In this particular case, another operational system already provided salespeople with current information about what they genuinely needed to know immediately. The more sophisticated customer analytics did not need the same refresh rate.
The lesson is straightforward: Refresh frequency should follow the rate of meaningful change and the decision being made, not somebody’s enthusiasm for a real-time dashboard.
3. The AI Worked. Understanding Its Cost Was Harder.
Processing unnecessary data has always been inefficient. Metered platforms add a new dimension: They put a cash register next to the inefficiency. AI adds another complication.
The AI in this system was doing useful work. We were asking it to analyze customer behavior and associations across a very large population, and that required a substantial amount of calculation behind the scenes. A lot of this was opaque to us. We could see the data going in. We could see useful analytics coming out. We could see credits being consumed. What we could not clearly see was everything happening between those points.
The daily process kept running. The consulting project finished. The users liked the analytics. The credits kept disappearing. Eventually another term became increasingly important: Usage event.
What exactly was a usage event? We asked the vendor directly in a meeting that included company leadership and the consulting team. We never got a clear answer.
That is a problem.
If a system charges according to an abstract unit, you should be able to explain what that unit represents. Does reading a row count? Writing one? Transforming one? Joining datasets? Running an AI analysis against a million records? Does one request trigger hundreds or thousands of internal operations? And more importantly, you should be able to translate that activity back into dollars.
If the work occurs inside an AI system that customers cannot directly inspect, that responsibility becomes even more important. The issue is not that AI performs a lot of calculation. The issue is charging customers for those calculations through a unit they cannot clearly observe, predict, or translate into cost.
Game companies figured out the psychological side of this years ago. Instead of asking for $7.43, they sell gems, coins, points, energy, or some other virtual currency. Those currencies come in packages, and one package is usually positioned to look like the obvious value.
The amounts rarely align perfectly with what you actually consume. Need 1,100 credits? Maybe the packages are 1,000 and 2,500. Fall a little short and you buy more. Have some left over and those leftovers encourage you to keep using them. The abstraction creates distance between the activity and the money.
Enterprise software increasingly uses the same basic mechanism. Instead of saying an operation costs $14.72, it consumes some number of credits. You buy those credits in packages. One package looks especially attractive. You are told you have plenty. But plenty for what? If nobody can clearly explain what consumes those credits, “plenty” is not a useful measurement.
Gamers learned a long time ago to be suspicious of currencies that sit between an action and actual money. Corporate buyers should learn the same lesson.
4. When the Bill Arrived
Within roughly a year, the organization had spent close to a million dollars associated with this implementation. At that point, people became considerably more interested in the warning I had raised before launch. “What should we do?”
My first answer was simple: Shut it down and take some time to rewrite the routines. That was not popular because the people consuming the analytics had become accustomed to that near-real-time view. So they asked what the alternatives were.
I pointed back to the analytics platform we already had. It could do the same analytical work with a few modest changes to the integration path. It was not quite as direct, but it would work and still provide the analytics people wanted. That option would require some work from other data teams, so it was rejected as well.
Eventually, with the project money gone, the expensive implementation was shut down. The obvious question is: If I already had much of the logic running elsewhere, why didn’t I simply finish moving the work back? I was preparing to pursue another path when an organization-wide return-to-office policy eliminated my remote role. The work stopped with my departure. That is relevant here only because it explains why an apparently obvious technical alternative did not become the final solution.
5. The People Closest to the Work Often Know Something Important
The ultimate problem was not caused by one decision made by one person. The consultants reused an implementation that worked, but their version continued processing the full customer population rather than adapting to how slowly the underlying data actually changed. Sales and Marketing wanted extremely fresh data. Leadership trusted assurances from the consultants and the platform vendor that there were plenty of credits. The vendor told us we had plenty of credits but could not clearly explain what would consume them.
And somewhere in that chain, nobody really owned the most important question: How much of this data actually changes, and what does it cost to keep processing everything that did not? There is another lesson here that has very little to do with data architecture.
I warned people before this system went live. The consulting company understood its implementation. The platform vendor understood its product. Senior leadership understood the business objectives. But I knew how the data behaved. And I learned the principle here long before I worked in data.
When I directed automobile service departments, I routinely asked mechanics how work actually moved through the shop. I asked service advisers. I even asked the people washing the cars. And that shocked some owners and general managers.
Automotive service departments are often treated as the dealership’s dirty afterthought. They are literally dirty, they generate an enormous share of customer complaints, and operationally they are vastly more complicated than the sales floor.
Most dealership general managers come from sales. Many owners and managers want as little to do with service as possible. This is particularly strange because a good service department can generate a huge share of a dealership’s profit.
Consulting the mechanics is considered unconventional in some dealerships. Consulting the car washers is heresy. But if you want to know what’s really happening, the people at the bottom of the org chart often know things nobody upstairs does.
Some of the smartest people I have ever worked with were mechanics. And the car washers know everything. You just have to ask them.
The same principle applies in data. The person maintaining a data process knows which records actually change. The analyst closest to the source system often knows which fields are trustworthy and which are not. The people living with the process every day know where the friction actually is.
Executives need the high-level view. But altitude is not accuracy. Good leadership requires knowing when to come down from 80,000 feet and ask the people standing next to the machinery what it is actually doing.
Three Questions — and One More
Cloud computing, AI, tokenized services, metered platforms, and increasingly powerful analytical systems have made it possible to process extraordinary amounts of information very quickly. But that does not mean we should.
Before building a recurring data process, organizations should answer three questions:
First, how fast does the underlying data meaningfully change? A large dataset may be remarkably stable. Process the changes when possible instead of repeatedly rediscovering that everything stayed the same.
Second, how fresh does the answer actually need to be? Operational information may need to be instantaneous. Strategic analytics often do not. If nobody can identify the decision that benefits from real-time freshness, real time may simply be expensive impatience.
Third, what does the processing actually cost? If a vendor expresses cost in credits, tokens, usage events, or some other abstraction, translate those abstractions back into dollars. Then calculate what the architecture costs at the frequency and scale you actually intend to use. And if the vendor cannot or will not clearly explain what consumes those credits or tokens, that is a huge red flag.
There is one more question worth asking: What are the people closest to the work telling you?
Technology can make an inefficient idea run very fast. Cloud platforms can make it scale. AI can perform analytical work that would have been extraordinarily difficult only a few years ago. Metered billing will make every unnecessary operation cost money.
None of that eliminates the need to understand the data. It makes understanding the data more important.
The dataset may be large. But its rate of change may not be.